Reliability is not an accident. It is the result of deliberate design, disciplined maintenance, and continuous improvement. Plants that operate reliably for decades do so because reliability was engineered into them, not because they were lucky.
Reliability engineering is the discipline of understanding why equipment fails and applying that knowledge to prevent failures. It combines design, maintenance, operations, and data analysis into a single approach focused on keeping the plant available, efficient, and safe.
For small to medium-scale industrial plants, reliability engineering is especially valuable because there is less redundancy and fewer resources to absorb failures. A reliability-focused approach helps direct limited resources where they have the greatest impact.
This article covers the key concepts and practices of plant reliability engineering, from basic definitions to practical implementation.
What Is Plant Reliability?
Reliability is the probability that equipment or a system will perform its intended function without failure for a specified period under specified conditions.
In practical terms, reliability means:
- Equipment works when needed.
- Equipment works as designed.
- Equipment continues to work over time.
- Equipment works safely.
Reliability is not the same as availability, although the two are related.
| Term | Definition | Example |
|---|---|---|
| Reliability | Probability of performing without failure over a period | 90% probability of running 8,000 hours without failure |
| Availability | Percentage of time equipment is available for operation | 95% available over a year |
| Maintainability | Ease and speed of restoring equipment after failure | Average repair time of 4 hours |
| Relationship | Availability depends on both reliability and maintainability | High reliability and fast repair give high availability |
Availability depends on both how often equipment fails (reliability) and how quickly it is restored (maintainability). A pump that fails rarely but takes three weeks to repair can have worse availability than one that fails more often but is fixed in hours.
Why Reliability Engineering Matters
Reliability directly affects plant performance.
| Factor | Impact of High Reliability | Impact of Low Reliability |
|---|---|---|
| Production | Consistent output; commitments met | Unplanned outages; lost production |
| Cost | Predictable maintenance; lower emergency costs | High repair costs; premium purchases |
| Safety | Fewer failures; fewer incidents | Failures create safety hazards |
| Efficiency | Equipment performs as designed | Degraded performance; higher fuel cost |
| Reputation | Customer confidence maintained | Lost customers; damaged reputation |
| Morale | Team pride in a reliable plant | Firefighting culture; burnout |
Unplanned failures are also usually the most expensive kind. They bring lost production, expedited parts, overtime labor, and often collateral damage to other equipment. For small plants, where redundancy is limited, reliability is not optional. It is essential.
Key Reliability Concepts
Reliability engineering uses several fundamental concepts.
| Concept | Definition | Application |
|---|---|---|
| Failure rate | Frequency of failure over time | Predicts how often equipment will fail |
| MTBF | Mean time between failures (repairable equipment) | Average operating time between failures |
| MTTF | Mean time to failure (non-repairable items) | Expected life of items replaced rather than repaired |
| MTTR | Mean time to repair | Average time to restore equipment |
| Inherent availability | MTBF ÷ (MTBF + MTTR) | Percentage of time equipment is available, excluding planned maintenance |
| Failure mode | How equipment fails | Identifies how failures occur |
| Root cause | Fundamental reason for failure | Prevents recurrence |
| Bathtub curve | Failure pattern over equipment life | Guides maintenance strategy |
Worked example. A feed pump has an MTBF of 2,000 hours and an MTTR of 4 hours. Its inherent availability is 2,000 ÷ 2,004, or about 99.8%. If repairs took 40 hours instead, availability would drop to about 98.0%. This shows how much repair time matters.
A common misunderstanding. MTBF is not the expected service life of equipment. If failures occur randomly at a constant rate, only about 37% of units will still be running after operating for a period equal to the MTBF. MTBF is a statistical average across a population, not a guarantee for an individual machine.
The Bathtub Curve
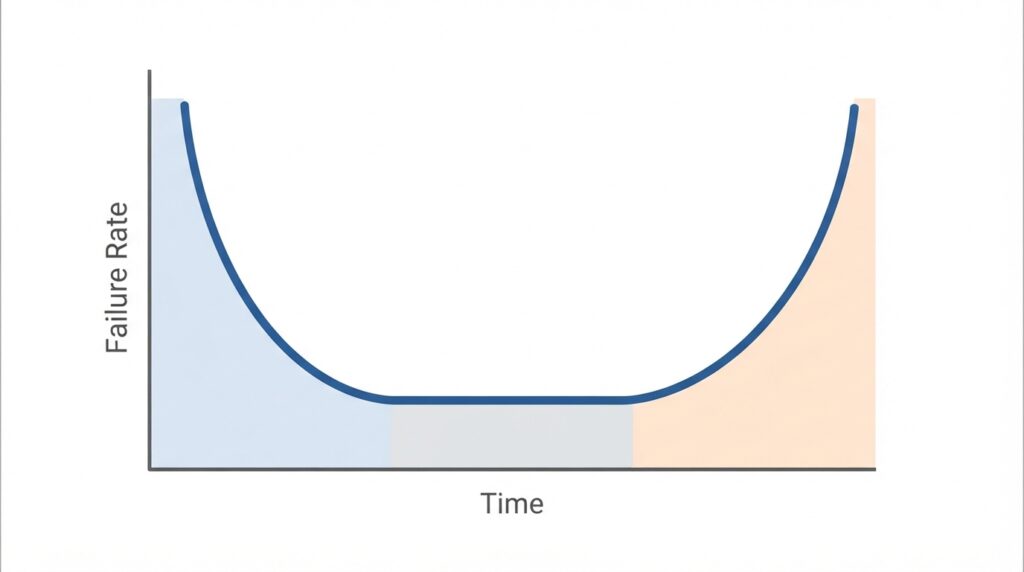
The bathtub curve describes one common failure pattern over an equipment’s life.
| Phase | Failure Pattern | Causes | Maintenance Strategy |
|---|---|---|---|
| Early life (infant mortality) | High failure rate, decreasing | Manufacturing defects, installation errors | Commissioning, burn-in, quality control |
| Useful life | Low, roughly constant failure rate | Random failures | Condition monitoring and condition-based tasks |
| Wear-out | Increasing failure rate | Aging, wear, fatigue | Overhaul, replacement, increased monitoring |
Understanding where equipment is on the curve helps select the right maintenance strategy.
An important caveat. The bathtub curve is a useful model, but it is not universal. Studies of failure patterns, most notably the aviation work behind reliability-centered maintenance, found that only a minority of components follow it. Many show infant mortality followed by a long, flat, random-failure period with no clear wear-out. For equipment with random failures, time-based overhauls do not reduce failures and can even introduce new ones through maintenance-induced errors. This is why condition-based approaches and failure data analysis matter.
Reliability vs. Maintenance
Reliability and maintenance are related but distinct.
| Aspect | Reliability Engineering | Maintenance |
|---|---|---|
| Focus | Preventing and reducing failures through design, analysis, and improvement | Preserving equipment function and restoring it when it is lost |
| Timing | Design, operation, and after failures (to prevent recurrence) | Scheduled, condition-based, and after failure |
| Approach | Analysis, design change, and improvement | Inspection, servicing, repair, and replacement |
| Goal | Eliminate or reduce failures | Keep equipment in service and minimize downtime |
| Discipline | Reliability engineering | Maintenance management |
Reliability engineering asks, “How do we prevent this failure?” Maintenance asks, “How do we keep this equipment working, and how do we fix it quickly when it stops?” Both are necessary, but reliability addresses the root of the problem.
Reliability Engineering Activities
Reliability engineering involves several core activities.
| Activity | Purpose | When Applied |
|---|---|---|
| Reliability prediction | Estimate failure rates and reliability | During design |
| Reliability block diagrams | Model system reliability and identify weak points | During design and modification |
| Criticality analysis | Rank equipment by consequence of failure | Design and operation |
| FMEA | Identify failure modes and effects | During design and operation |
| RCM | Determine maintenance requirements | Design and operation |
| RCA | Investigate failures and prevent recurrence | After failures |
| Condition monitoring | Detect developing failures | During operation |
| Reliability testing | Verify reliability through testing | During design and commissioning |
| Data analysis | Track and analyze failure data | Continuously |
| Reliability improvement | Implement changes to improve reliability | Continuously |
These activities work together to build and maintain reliability.
Reliability Block Diagrams (RBD)
Reliability block diagrams (RBDs) model how components are arranged in a system, in series, parallel, or a combination, to calculate overall system reliability. They help identify where redundancy improves reliability and where single points of failure exist.
- Series arrangement: All components must work for the system to work. System reliability is the product of component reliabilities. Two pumps in series, each with a reliability of 0.95, give a system reliability of 0.95 × 0.95 = 0.9025.
- Parallel arrangement: The system works if at least one component works. Two parallel pumps, each with a reliability of 0.95, give a system reliability of 1 − (0.05 × 0.05) = 0.9975.
The comparison shows two things. In a series arrangement, every added component lowers system reliability. In a parallel arrangement, redundancy raises it substantially. RBDs also reveal that a highly reliable redundant pair can still be undermined by a shared, single-point component such as a common suction header, a shared power supply, or a single control system. Simple RBD calculations assume independent failures. Common-cause failures, such as a shared utility loss, can defeat redundancy and should be considered separately.
Criticality Analysis
Criticality analysis ranks equipment by the consequences of failure: safety, environmental, production, and cost. It helps direct reliability resources to the equipment that matters most.
A simple approach scores each asset for the severity of failure consequences and the likelihood of failure, then ranks assets by the combined score. Equipment is often grouped into categories such as:
- Critical: Failure threatens safety, the environment, or production. These assets receive the full set of reliability practices, including FMEA, condition monitoring, and critical spares.
- Important: Failure causes significant but manageable impact. These assets receive planned preventive and predictive tasks.
- Standard: Failure has limited consequences. These assets may be run to failure or maintained at low cost.
For small plants, criticality analysis is often the single most valuable first step, because it focuses limited effort where it counts.
Reliability in Design
Reliability starts with design. The choices made during design determine the reliability the plant can achieve.
Design for reliability principles:
- Simplicity: Fewer components mean fewer failure points.
- Redundancy: Backup equipment for critical functions. Redundancy improves reliability but adds cost, complexity, and its own failure modes (such as standby equipment that fails to start), so it should be applied selectively.
- Derating: Operating equipment below maximum ratings extends life.
- Material selection: Materials suited to the operating environment.
- Standardization: Common components reduce variety and simplify maintenance and spares.
- Accessibility: Equipment accessible for inspection and maintenance.
- Design margins: Adequate margin for uncertainty and variability.
- Fault tolerance and fail-safe design: Systems that fail to a safe state and tolerate single faults.
Reliability cannot be fully added after design. It must be designed in. Reliability can be improved later through modifications, but at greater cost and with less effect.
Reliability in Operation
Once the plant is operating, reliability depends on how it is operated and maintained.
Operational factors:
- Operating within design limits: Avoiding conditions outside the design envelope.
- Proper startup and shutdown: Following procedures to minimize stress.
- Load management: Avoiding rapid load changes that stress equipment.
- Monitoring: Watching for signs of degradation.
- Feedback: Reporting problems before they become failures.
- Operator care: Routine rounds, cleanliness, lubrication checks, and early reporting of abnormal sounds, leaks, or vibration.
Maintenance factors:
- Preventive maintenance: Performing scheduled tasks.
- Predictive maintenance: Monitoring condition and acting on findings.
- Corrective maintenance: Repairing failures promptly and correctly.
- Spare parts: Having the right parts when needed.
- Documentation: Maintaining records that support analysis.
- Quality of work: Correct procedures, torque values, alignment, and cleanliness, since poor workmanship is itself a common cause of failure.
Operation and maintenance determine whether the design reliability is achieved in practice.
Condition Monitoring and Predictive Maintenance
Condition monitoring is a key reliability practice. It detects developing failures before they cause equipment to stop.
Common monitoring techniques:
| Technique | Detects | Application |
|---|---|---|
| Vibration analysis | Bearing wear, imbalance, misalignment | Rotating equipment |
| Thermography | Hot spots, loose connections, overheating | Electrical panels, bearings |
| Oil analysis | Wear particles, contamination | Gearboxes, engines, turbines |
| Ultrasonic testing | Leaks, thickness loss, bearing defects | Piping, tanks, vessels |
| Performance monitoring | Efficiency loss, fouling | Heat exchangers, compressors |
| Motor current analysis | Motor and driven equipment faults | Motors, pumps, compressors |
| Partial discharge testing | Insulation deterioration | Transformers, switchgear, medium- and high-voltage motors and cables |
| Dissolved gas analysis | Internal transformer faults | Oil-filled transformers |
Electrical equipment. Electrical equipment, such as motors, transformers, and switchgear, also benefits from condition monitoring. Partial discharge testing, infrared thermography, and motor current analysis detect developing faults before they cause failure.
The P-F interval. Condition monitoring works because most failures do not happen instantly. The point at which a developing problem becomes detectable (P) comes before functional failure (F). The time between the two is the P-F interval. Monitoring must be performed more often than the P-F interval, with enough warning time left to plan the repair. A vibration check every six months is of little use for a bearing whose P-F interval is a few weeks.
Condition monitoring allows maintenance to be performed when needed, not on a fixed schedule.
Reliability Data and Analysis
Reliability engineering depends on data.
Data sources:
- Failure records: What failed, when, and why.
- Maintenance records: What was done, when, and by whom.
- Operating data: How equipment was operated.
- Condition monitoring data: Trends and anomalies.
- Design data: Specifications and expected performance.
Analysis methods:
- Failure rate analysis: How often does equipment fail?
- Trend analysis: Is reliability improving or degrading?
- Pareto analysis: Which failures cause the most problems? Often a small number of equipment items or failure modes account for most of the lost production.
- Weibull analysis: What is the failure pattern? The Weibull shape parameter (β) indicates the pattern: β below 1 suggests early-life failures, β near 1 suggests random failures, and β above 1 suggests wear-out.
- Root cause analysis: Why did the failure occur?
Good data starts with consistent failure coding in the maintenance system. If work orders record only “repaired pump,” there is nothing to analyze. Recording the equipment, failure mode, cause, and downtime makes later analysis possible.
Data without analysis is just records. Analysis turns data into insight.
Reliability Metrics
Reliability is measured with several key metrics.
| Metric | Definition | Target |
|---|---|---|
| MTBF | Mean time between failures | Increasing over time |
| MTTR | Mean time to repair | Decreasing over time |
| Availability | Percentage of time available | 95%+ for most plants (varies by plant type) |
| Reliability | Probability of performing without failure | Application-specific |
| Failure rate | Failures per unit time | Decreasing over time |
| OEE | Overall equipment effectiveness (availability × performance × quality) | 85%+ for world-class |
Metrics should be tracked over time to identify trends and improvement opportunities. They should also be applied to defined equipment groups, since a plant-wide average can hide a few chronic bad actors.
Reliability Improvement
Reliability is not static. It must be continuously improved.
Improvement approaches:
- Root cause analysis: Investigate failures and prevent recurrence.
- FMEA: Identify failure modes and address them.
- RCM: Optimize maintenance based on failure modes.
- Reliability-centered design: Apply reliability principles to modifications.
- Benchmarking: Compare against similar plants.
- Best practices: Apply proven practices from industry.
- Training: Build reliability skills in the team.
- Culture: Make reliability a core value.
Reliability-Centered Design for Modifications
When equipment is modified or replaced, reliability principles should be applied to the new design. A modification that solves one problem but introduces another is not an improvement.
In practice, this means:
- Reviewing the failure history that prompted the change, so the modification targets the root cause rather than a symptom.
- Applying a management of change (MOC) process so that effects on other equipment, operating procedures, and safety systems are assessed.
- Considering maintainability, spares, and standardization for the new equipment, not just performance.
- Updating drawings, procedures, and maintenance plans, and verifying the result after the change.
Reliability improvement is a journey, not a destination.
Building a Reliability Culture
Reliability is not just a technical discipline. It is a culture.
Elements of a reliability culture:
- Leadership commitment: Reliability is a priority, not just a slogan.
- Data-driven decisions: Decisions based on evidence, not opinion.
- Proactive mindset: Fixing problems before they cause failures.
- Continuous learning: Capturing and applying lessons.
- Accountability: Everyone owns reliability in their area.
- Collaboration: Operations, maintenance, and engineering work together.
- Patience: Reliability improvements take time.
A reliability culture is what sustains reliability over the long term.
Reliability in Small Plants
Small plants face particular challenges with reliability.
Challenges:
- Fewer resources for reliability programs.
- Limited data for analysis.
- Less specialist expertise.
- Competing priorities.
Practical approaches:
- Focus on critical equipment: Use criticality analysis to apply reliability practices where they matter most.
- Use simple tools: MTBF, MTTR, and failure tracking provide value without complexity.
- Start with RCA: Investigate significant failures and prevent recurrence.
- Use condition monitoring selectively: Apply it to critical rotating and electrical equipment.
- Build skills gradually: Train the team on reliability basics.
- Learn from others: Apply lessons from similar plants and from equipment suppliers.
- Make it a habit: Reliability practices become routine over time.
A practical starting sequence is: (1) rank equipment by criticality, (2) set up consistent failure recording, (3) track MTBF, MTTR, and downtime for critical equipment, (4) perform RCA on significant failures, (5) add condition monitoring where it is most valuable, and (6) review results regularly and expand gradually.
Small plants can achieve high reliability with focused effort and simple tools.
Common Mistakes in Reliability Engineering
Even experienced organizations make mistakes. Common ones include:
- Focusing on maintenance only: Reliability starts with design.
- Reacting instead of preventing: Firefighting culture instead of proactive reliability.
- Ignoring data: Making decisions without evidence.
- Skipping RCA: Fixing symptoms instead of causes.
- No metrics: Not measuring reliability or tracking improvement.
- Over-maintaining: Performing unnecessary tasks, which wastes resources and can introduce errors.
- Under-maintaining: Skipping needed tasks.
- Treating all equipment equally: Failing to prioritize by criticality.
- Misreading MTBF: Treating it as guaranteed life rather than a statistical average.
- No culture: Reliability treated as a project, not a value.
These mistakes keep plants in a cycle of failures and repairs.
How Japanese EPC Firms Approach Reliability
Japanese engineering firms are known for their disciplined approach to reliability. Common characteristics include:
- Design for reliability: Reliability is designed in from the start.
- Thorough documentation: Records support analysis and improvement.
- Disciplined maintenance: Procedures are followed consistently.
- Continuous improvement: Lessons are captured and applied.
- Long-term focus: Reliability is a long-term commitment, not a short-term goal.
- Culture: Reliability is embedded in how people work.
For plant owners, this often means plants that perform reliably for decades.
How to Evaluate Reliability Readiness
When reviewing reliability for your plant, ask:
| Question | Why It Matters |
|---|---|
| Is reliability a design priority? | Reliability starts with design |
| Has criticality analysis been performed? | Focuses effort on the equipment that matters most |
| Are reliability metrics tracked? | What gets measured gets improved |
| Is condition monitoring in place for rotating and electrical equipment? | Detects problems before failures |
| Is RCA performed for significant failures? | Prevents recurrence |
| Is FMEA applied to critical equipment? | Identifies failure modes proactively |
| Is RCM used to optimize maintenance? | Directs effort where it matters |
| Are single points of failure identified? | RBDs reveal where redundancy is needed |
| Are modifications reviewed for reliability impact? | Prevents new problems from being introduced |
| Is there a reliability culture? | Sustains reliability over time |
| Is there continuous improvement? | Keeps reliability from degrading |
A plant that addresses these questions is likely to achieve high reliability.
Conclusion
Reliability engineering is the discipline of understanding why equipment fails and applying that knowledge to prevent failures. It combines design, maintenance, operations, and data analysis into a single approach.
For small to medium-scale industrial plants, reliability engineering is especially valuable because there is less redundancy and fewer resources to absorb failures. By focusing on design, criticality, condition monitoring, RCA, and continuous improvement, plants can achieve the reliability that keeps them productive and safe.
Key Takeaways
- Reliability is engineered, not accidental.
- Reliability is the probability of performing without failure; availability also depends on maintainability.
- The bathtub curve describes one common pattern of failure over equipment life, but not all equipment follows it.
- Reliability engineering includes prediction, RBDs, criticality analysis, FMEA, RCM, RCA, and condition monitoring.
- Design determines the reliability a plant can achieve, and modifications must be reviewed so they do not introduce new problems.
- Condition monitoring applies to electrical equipment as well as rotating equipment.
- Metrics like MTBF, MTTR, and availability track reliability performance, and MTBF is an average, not a guaranteed life.
- A reliability culture sustains reliability over the long term.
- Japanese EPC firms emphasize design for reliability and continuous improvement.